Crux Labs, a New York software startup founded to improve how enterprise AI agents make decisions in complex industries, launched out of stealth on 29 October 2026 with over $6 million in seed funding. The round was co-led by venture capital firms Benchstrength and Misneach, with backing from Analog Ventures and Pareto Holdings.
Key points
- Crux Labs has secured more than $6 million to bridge the divide between software engineers building autonomous systems and the domain specialists who evaluate them.
- Current deployment workflows force companies to audit as little as 1% of operational logs manually, leaving the vast majority of agent errors undetected.
- The company uses internal evaluator agents to capture employee heuristics and run calibrated assessments across total production traffic.
- Early trials cover organisations in healthcare, cybersecurity and financial services, where subtle reasoning mistakes carry severe regulatory or clinical costs.
- The founders previously led engineering and deployment initiatives at Meta, Tractable AI, Checkr and Block Renovation.
The problem with monitoring production agents
As businesses move from simple conversational chatbots to autonomous agents that execute multi-step workflows, managing quality has become an acute technical hurdle. A customer service or claims processing agent might interact with external databases, call specialised software tools, write code and resolve requests without direct human oversight. These deployments generate thousands or millions of operational traces every day.
Existing monitoring tools allow software engineers to view traces, tracking the precise sequence of prompts, model outputs, API calls and system errors. What those tools cannot do is determine whether the agent made a sensible decision in the context of the business. An agent may return an articulate, technically valid answer that violates an unwritten operational standard, misinterprets clinical nuance or neglects to escalate a sensitive fraud case.
Because manual review requires skilled staff whose time is limited, organisations often inspect a tiny sample of their total workload. Crux Labs estimates that engineering teams typically review 1% or less of agent interactions, choosing logs through random sampling or blunt performance thresholds. As a result, unusual edge cases and systemic errors can linger unnoticed in production pipelines for weeks until an external user reports a failure.
How Crux turns staff intuition into software tests
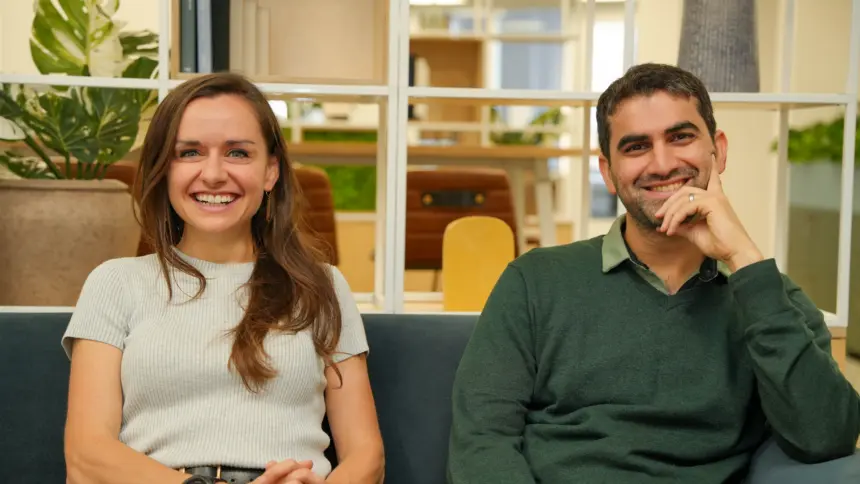
Founded by Julie Kheyfets and Krishna Kulkarni, Crux Labs addresses this bottleneck by embedding its platform directly into existing enterprise communication and ticketing tools. Rather than demanding that domain experts write code or fill out tedious audit spreadsheets, the software captures the informal heuristics that experienced professionals rely on when reviewing work.
The platform deploys its own internal agents to act as evaluators. These systems ingest the feedback, corrections and decisions made by senior staff, translating subjective judgment into quantifiable benchmarks. Once calibrated, these automated evaluations monitor full production streams continuously, flagging deviations and alerting engineering teams without relying on thin statistical sampling.
“Aligning AI agents to human judgment is one of the biggest challenges of our time,” Kheyfets said. She noted that while autonomous models excel at solving bounded goals, they lack the accumulated rules of thumb that human professionals acquire over years of working within specialised sectors.
Automating evaluation across an entire traffic stream presents its own engineering challenges. An automated evaluator that reviews every single log entry can still produce false positives or miss novel failure modes if its evaluation criteria are poorly aligned with real business needs. To counteract this, Crux continually updates its evaluation models as human workers resolve new anomalies, attempting to keep the oversight system as dynamic as the operating environment.
Why domain expertise matters in regulated sectors
The gap between software construction and operational execution is particularly acute in heavily regulated sectors such as healthcare, financial services and cybersecurity. In these fields, an agent failure is rarely as simple as a broken server connection or an unhandled software exception; it often involves a misjudged risk or a misapplied policy.
A cybersecurity agent might triage an incoming security alert and close it because the technical parameters appear normal, failing to notice a subtle lateral movement pattern that an experienced threat analyst would spot immediately. Similarly, in healthcare administration, an agent handling prior authorisation requests may misinterpret insurance policy criteria, causing improper claim rejections that take administrative staff weeks to unpick.
“Engineering teams know how to build AI agents, and subject matter experts know what success looks like,” Kulkarni said, pointing out that businesses have struggled to construct a functional technical bridge between those two groups.
Crux reported early adoption among high-growth startups and Fortune 500 corporations operating in complex fields, though the company has not yet released specific customer identities, usage metrics or revenue numbers. Its immediate commercial goal is to shorten the diagnostic cycle, ensuring that engineering teams can ship prompt adjustments, guardrail modifications and workflow patches hours after an issue appears rather than waiting for formal bug tickets.
The team and backing behind the launch
The company’s founding team brings direct experience from enterprise machine learning deployments and software scaling. Kheyfets and Kulkarni met as students at Princeton University. Kheyfets previously served as the head of North America for Tractable AI, an applied computer vision firm, and was chief executive of renovation platform Block Renovation.
Kulkarni held engineering leadership positions across major consumer and enterprise platforms. He led brand engineering at Meta, managed machine learning product development at background check provider Checkr, and helped scale digital health platform Healthify to 20 million patients before its acquisition.
Investors participating in the oversubscribed seed round are backing the thesis that post-deployment agent reliability represents the next major software category. The financing was co-led by Benchstrength and Dublin-based artificial intelligence investment fund Misneach, with participation from Analog Ventures and Pareto Holdings.
The investment reflects broader industry recognition that deploying foundation models into corporate workflows requires far more than raw model capability. As commercial models from major providers become cheaper and more capable, enterprise value is migrating toward the infrastructure that governs decision quality, auditability and domain alignment in everyday production.
What happens next for agent evaluation
Crux Labs plans to use the new capital to expand its research and engineering staff in New York and speed up deployments across corporate client environments. The company faces an expanding field of developer tools, as observability providers and evaluation frameworks compete to establish standard protocols for agent inspection.
The company’s central operational test will be proving that its automated evaluator agents can maintain alignment across diverse corporate cultures without generating excessive administrative overhead. If domain experts must constantly retrain the oversight system, the efficiency gains of deploying autonomous workers quickly evaporate.
For enterprise technology leaders, the emergence of dedicated judgment platforms highlights a broader shift in artificial intelligence operations. The immediate challenge is no longer assembling an agent that can browse the web or run scripts, but proving that the software behaves reliably enough to represent the organisation without constant direct human intervention.